Thirty hours.One human.Twenty-four agents.
A Go data-access layer, a secured REST API, and an identity-provider connector: designed, argued over, built, deployed to a real Kubernetes cluster, and reviewed live. It is still running. You can drive it yourself in the next four minutes, then read every word the agents said while building it.
loginid-takehome.uplifttech.org · live · db: okDrive the real API yourself
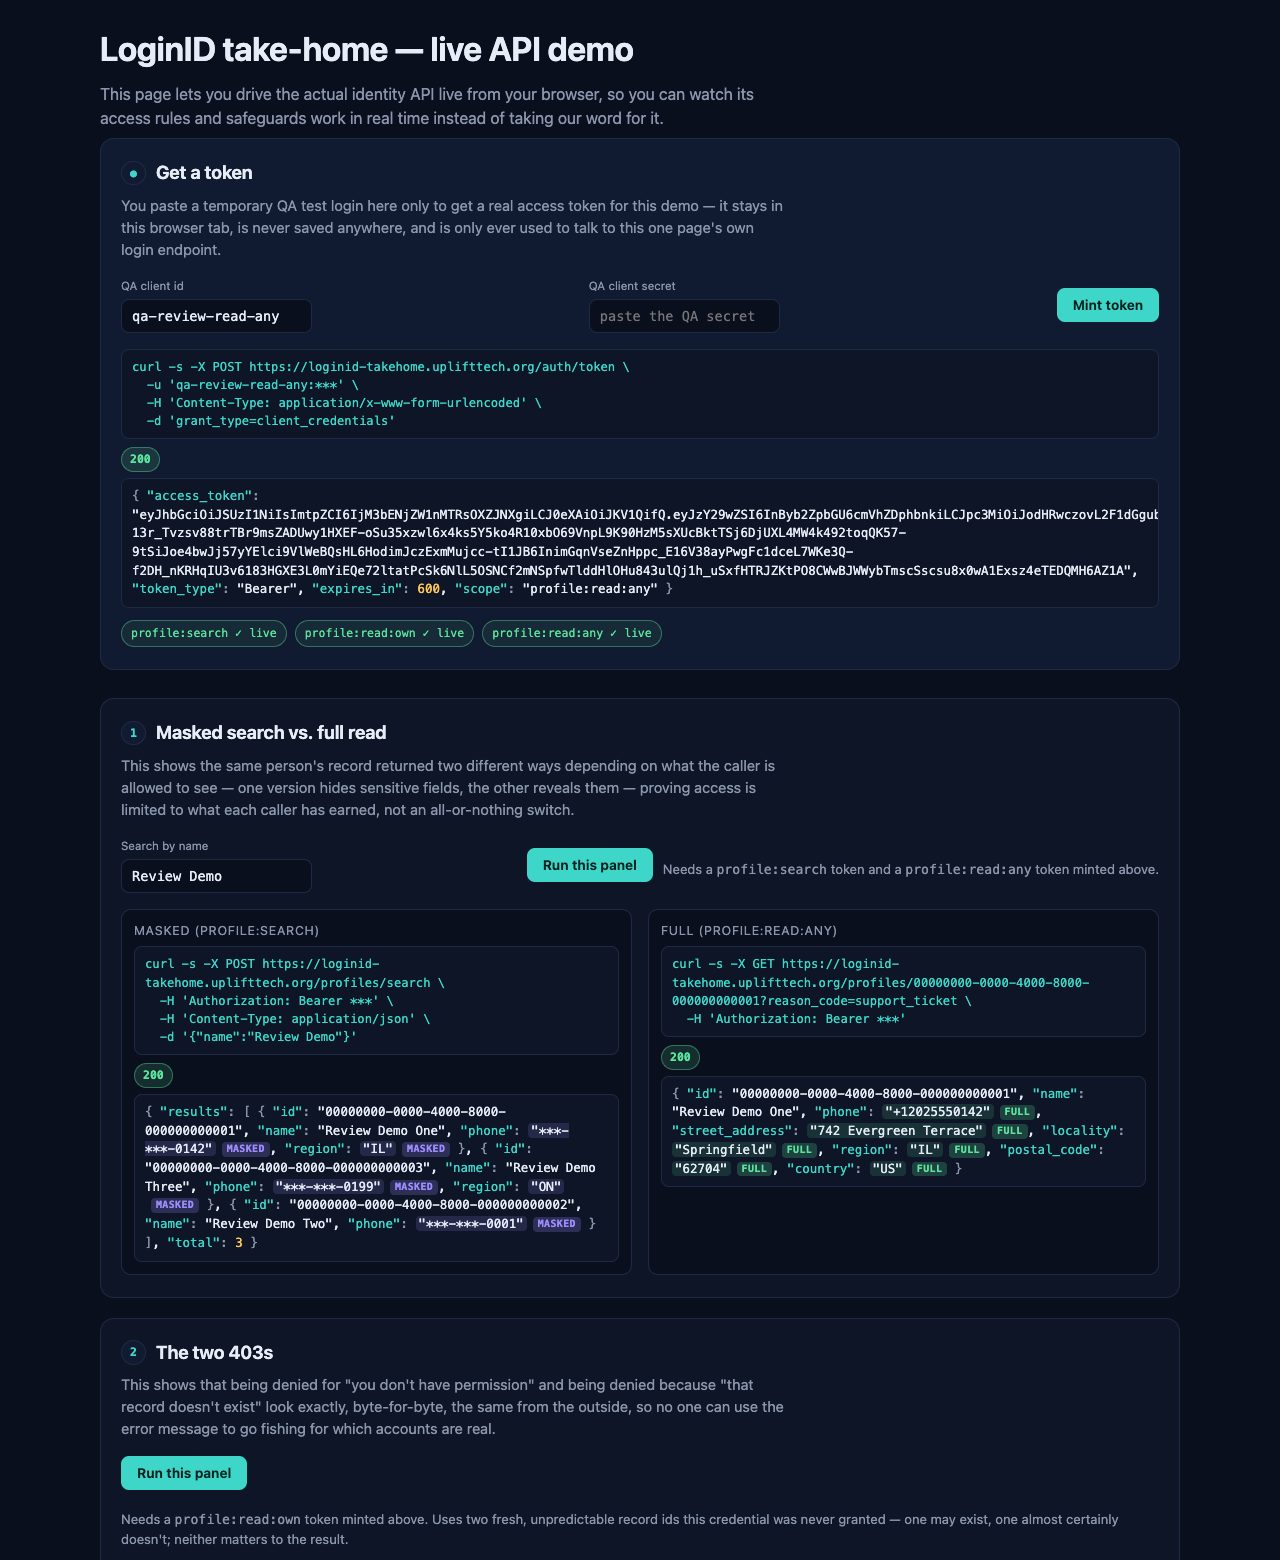
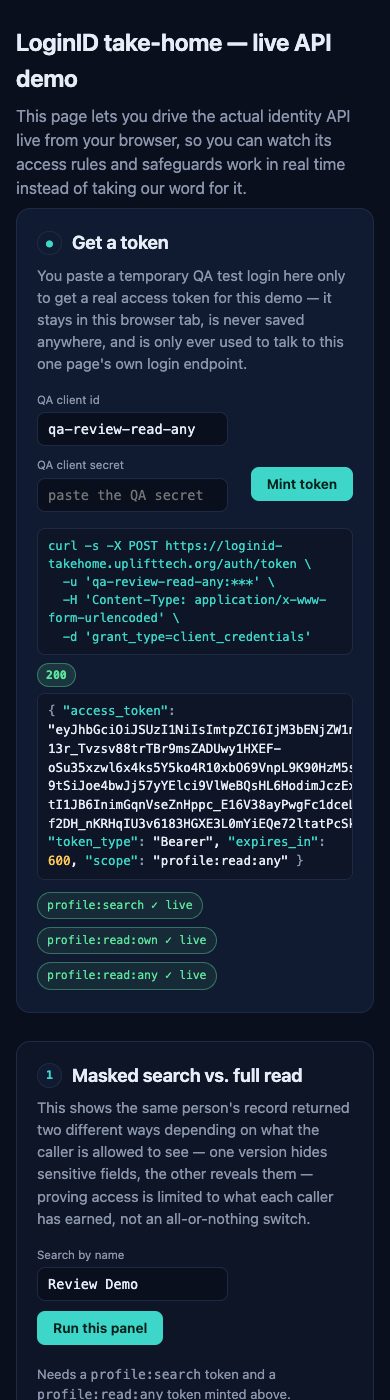
The assignment asked for three things: a multi-database DAO, a secured REST service to search and retrieve profiles, and a connector to a third-party identity provider. All three are running right now on a Kubernetes cluster. The demo console is a single page served by the API binary itself, on the same origin, so it holds no secret and needs no CORS. It makes real calls with a real token and prints the request as a curl line beside the raw response.
What you can try with no credentials at all
Open these in any browser, right now.
The health endpoint
Reports the build SHA running in the cluster and whether the database connection is live. The SHA always matches the tip of main, because deployment is the only way code reaches the cluster.
curl -s https://loginid-takehome.uplifttech.org/healthz
{"status":"ok","service":"api-service","build":"…","db":"ok"}
The refusal to answer without a token
Panel 3 on the demo page needs nothing from you. An unauthenticated read returns 401 with no hint about whether the record exists.
curl -i https://loginid-takehome.uplifttech.org/profiles/00000000-0000-4000-8000-000000000001
HTTP/2 401
Everything else needs a token, because the API has no anonymous read path. That is the design, not a gate on the demo.
Getting a credential
Three QA client credentials exist, each granted exactly one scope.
| Credential | Scope it carries | What it can do |
|---|---|---|
| QA search client | profile:search | Search by name. Phone and region come back masked. |
| QA read-own client | profile:read:own | Read only records this client owns. Used to produce the two identical 403s. |
| QA read-any client | profile:read:any | Full unmasked read, but only with a valid reason_code. |
These three clients exist only so a reviewer can drive the console with nothing else to set up. Each is scoped to one permission, points at fictional review rows, is rate-limited, and can be revoked in one SQL statement whenever this demo is retired.
| Client id | Client secret | Scope |
|---|---|---|
| qa-demo-search | de2b087e4d1a70406a9038f3a90300c4e2b7cece | profile:search |
| qa-demo-read-own | caf2769fdc521d5daa0b6bc0ce5c2bd46c43d16a | profile:read:own |
| qa-demo-read-any | 788fb14402e6fc3cb7679fb0eb9a7f28234fa195 | profile:read:any |
Running the console, step by step
About four minutes. Nothing you type is stored: the credential lives in the browser tab and dies with it.
Open the console
Go to loginid-takehome.uplifttech.org/demo. You will see one credential box at the top and five numbered panels below it, each with its own Run button.
Mint your first token
Paste the QA search client id into QA client id and its secret into QA client secret, then press Mint token. A green chip appears reading profile:search ✓ live. The page shows you the exact request it just made.
POST /auth/token
Authorization: Basic <client-id>:<client-secret>
Content-Type: application/x-www-form-urlencoded

grant_type=client_credentials
There is no scope parameter to send. The scope is a property of the credential, stored server-side, so a caller cannot ask for more than it was granted. Tokens last ten minutes; if one expires mid-review the page tells you to mint another rather than showing you a bare 401.
Repeat for the other two credentials
Paste the read-own pair, mint; paste the read-any pair, mint. You now hold three live tokens, one per scope, and three green chips. Clearing the fields does not clear the tokens.
Panel 1 — masked search beside full read
Leave the search box at its default, Review Demo, and press Run. Three fictional records come back: Review Demo One, Two and Three. In the left-hand response, phone and region are masked and highlighted as such. The page then re-reads the same record with the read-any token, and the right-hand response shows those fields in full.
The point is that authorisation is graduated, not a switch. The same row, the same handler, two different callers, two different shapes of truth.
POST /profiles/search   Authorization: Bearer <profile:search token>
{"name": "Review Demo"}

GET /profiles/{id}      Authorization: Bearer <profile:read:any token>
Panel 2 — the two identical 403s
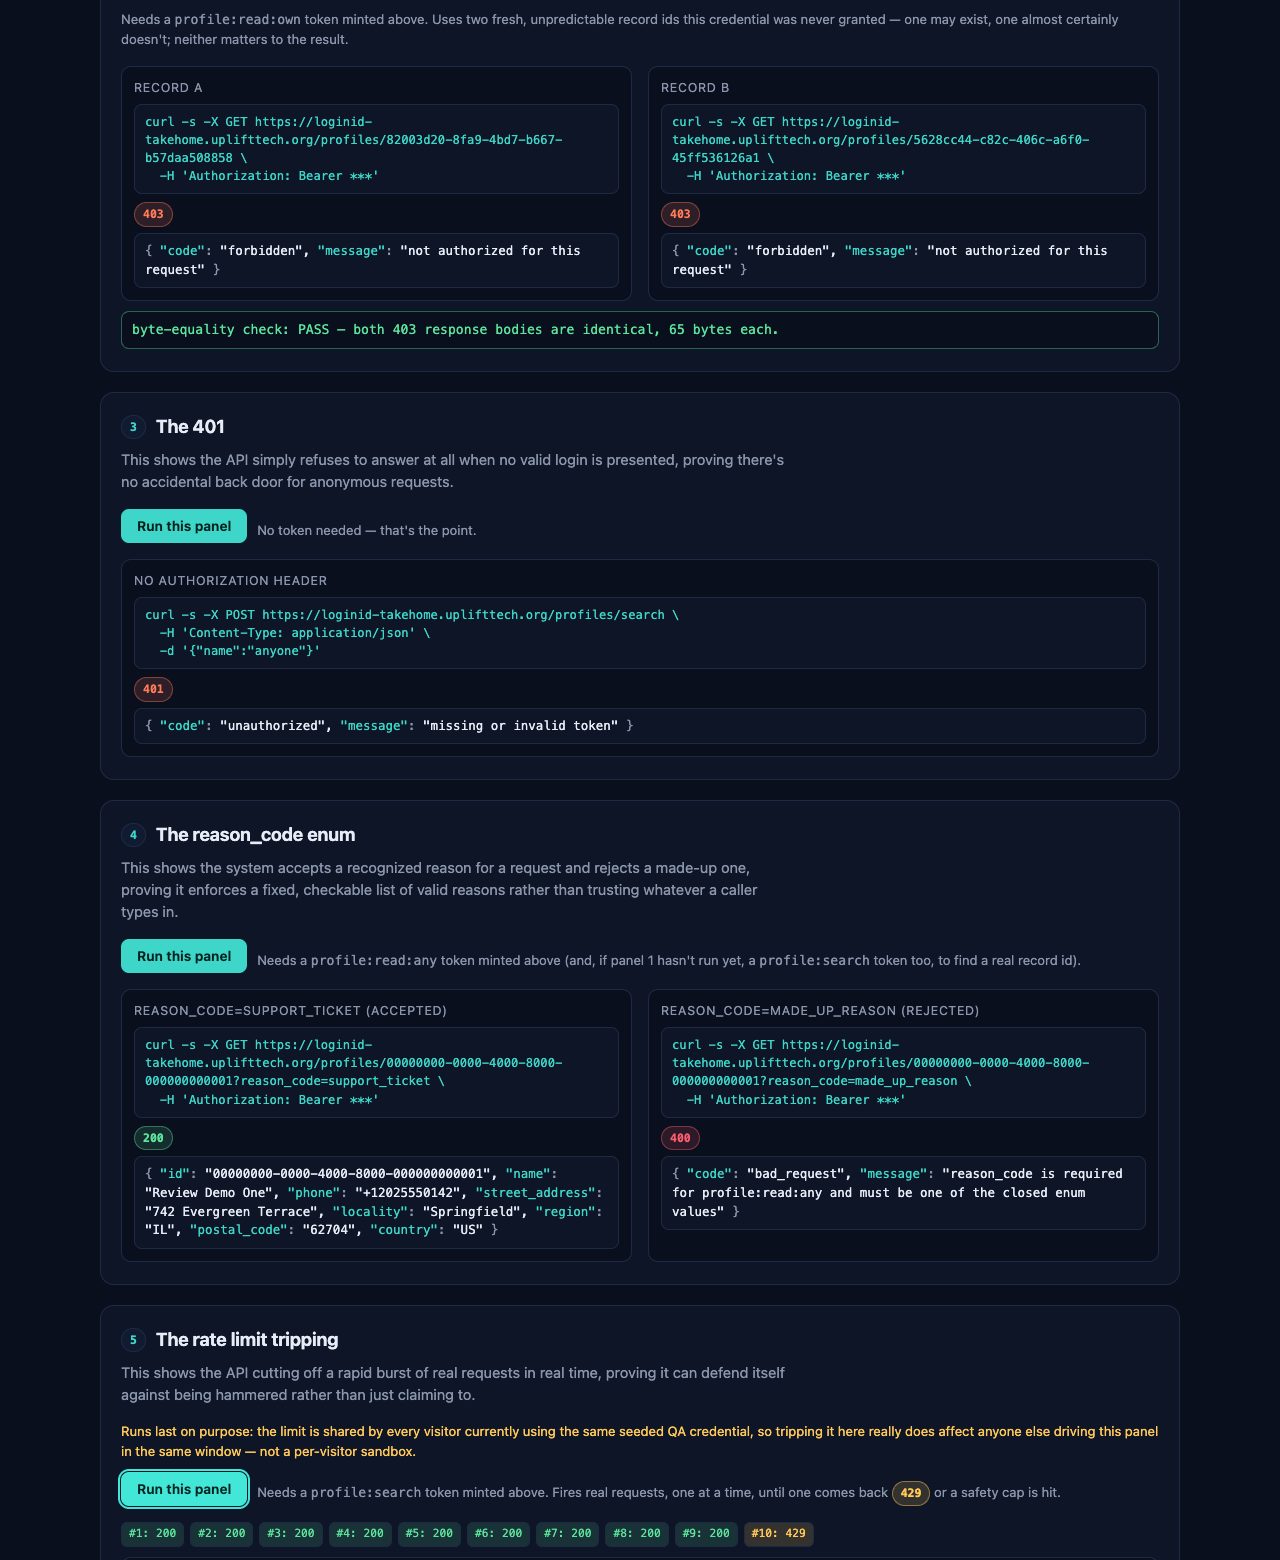
Press Run. The page requests two record ids the read-own credential was never granted: one that exists and one that almost certainly does not. Both come back 403 with the same 65-byte body, and the page compares them byte for byte in front of you and prints PASS.
If "you may not see this" and "this does not exist" looked different, an attacker could enumerate which customers are real by reading error messages. They do not look different.
Panel 3 — no token at all
Press Run with nothing minted. 401. There is no anonymous back door, including on the search path.
Panel 4 — the reason-code enum
Press Run. A full read is attempted twice with the read-any token: once carrying reason_code=support_ticket, which is on the server's closed list and is accepted, and once carrying reason_code=made_up_reason, which is rejected.
An unmasked read of someone's home address should require a stated, checkable purpose that gets written to the audit log. A free-text field would let the caller write anything; a closed enum will not.
Panel 5 — tripping the rate limiter, for real
Run this one last. The page fires real requests one at a time until the API answers 429, then stops. The limiter is shared across everyone using that QA credential, so if a colleague is on the page at the same moment you will both feel it. That is stated on the page rather than hidden behind a per-visitor sandbox.
Prefer a terminal? Every request above is printed on the page as a copyable curl line, so the console doubles as documentation for the API.
What the product owner saw when she signed it off
The console was the forty-third and last story, pulled after the backlog had already closed because a reviewer should be able to see the thing work, not read that it works. The human added one requirement: make sure it looks good.
One honest limitation went into the record: the page sets every autofill hint the platform offers, and a browser-extension password manager still offered to save the QA credential, because extensions use their own heuristics and ignore those hints. The control that actually holds is that the credential is single-scope, low value, and revocable by runbook.
Who was working, what it cost, what happened
Everything here follows the playhead. Agent tiles glow with the tokens they generated in the current hour; the bars are dollars per hour by role, the green line is stories Done, coral ticks are human decisions; the feed shows the moment on the tape.
The org, live
Brightness = output tokens this hour. Bar = share of that persona's total so far.
On the tape
Sixty-eight log entries compressed to the moments that changed something.
Dollars per hour, stories Done, human decisions
Bars stacked by role (PM, leads, hires, research). Right axis: cumulative stories. Coral ticks: the 27 human decisions. Grey band: usage pause.
Thirty-one hours × twelve seats
Output tokens per hour per seat, drawn from the transcripts. Leads run hot all day; hires flare during refinement and review; the PM is a steady line, which is what orchestration looks like from above.
Color scale is per row (each seat relative to its own busiest hour), so a hire's flare and a lead's marathon both read.
Tokens → models → roles → dollars
Ribbon width is dollars at the prices set below. Cache reads make up most of the input and most of the cost; the orchestrator's model is the priciest per token but read the least.
What thirty hours cost
Every transcript records per-turn usage split into fresh input, cache reads, cache writes, and output. Multiplied by list price per model, that is the bill. Haiku's prices are published; Sonnet 5, Opus 5, and Fable 5.1 are assumptions, marked, and editable.
Spend by role
Leads carried the context; the PM's model costs the most per token.
Spend by model
Segments: cache read · cache write · output · fresh input.
Spend by seat
Leads and PM individually; each track's hires aggregated.
Prices, USD per million tokens
Edit any field; every figure on the page recomputes.
Where the human actually sat
Twenty-seven recorded decisions and no code. The split below is counted from LOG.md, Jira, and the session record.
Actions by origin
Each row is a kind of action; coral is the human's share.
Merge commits carry Warren's GitHub identity because the PM merged through his authenticated session; they are agent actions and counted as such.
The twenty-seven decisions
What only the human could decide.
| Kind | # | Examples |
|---|---|---|
| Direction | 6 | code go as an agile loop; the real cluster; attribution rule; org topology; teardown timing; "ask Amber what the cluster already has" |
| Rulings | 4 | Vault instead of etcd encryption; audit-log RBAC as accepted residual; Filebeat drop-filter fix; LT-20 disposition (pending) |
| Permission grants | 9 | Amber into Vault; two deployer Role updates; deleting six Secrets; classifier approvals for cluster mutations |
| Routing | 3 | DNS and GitHub credentials to Amber; Vault access via Amber; "she is logged in and can drive" |
| Cadence | 5 | "usage has reset, keep going" ×5 |
What runs in the namespace
Two Go binaries in three images. Watch the requests: a client mints a token at the issuer, calls the verifier, which checks the JWKS in-cluster and reads Postgres; the verifier alone may reach the connector; Vault feeds every pod its secrets at start. Hover a node for what it does.
Q1 · Data access
DAO for user_profile and user_credential
One Repository interface, three backends. A conformance suite runs identical assertions against real Postgres, CockroachDB, and SQLite containers in CI, including CockroachDB's serialization retry. Errors by SQLSTATE, never by message text.
Q2 · REST + auth
Search and retrieve, secured
OAuth2 client credentials mint RS256 tokens with per-client audiences; the verifier checks issuer, audience, and JWKS with bounded staleness. Masked search; full reads need read:own or read:any with a closed reason code; scope and policy denials are byte-identical 403s.
Q3 · IDP connector
/auth and /identity to a vendor
Vendor tokens fetched, used once, discarded. Uniform-timing failures, per-identity and overflow backoff; the failure-ratio limiter fired live in review. Reachable only from api-service.
How the work was actually organised
LoginID asked which AI tools were used and how. The honest answer is longer than a tool name, so this section gives the whole design: the layers, the model chosen for each seat and why, the rules that kept the agents from simply agreeing with each other, and a plain statement of which parts are Anthropic's documented patterns and which parts this project invented.
Why these choices were the right call, not just a choice
Every design decision below was made against a specific cost, and paid for itself. This is the part worth reading if you're deciding whether this person can run an AI-driven team, not just prompt one.
Fable 5.1 costs five times what Sonnet 5 costs per token. Putting Fable only on the one seat that holds cross-track state, instead of on all six leads, is the difference between an orchestrator premium and an organisation-wide one. The cost breakdown below shows leads and hires, not the manager, carried most of the token volume — exactly the seats where the cheaper model was the correct call, not a corner cut.
99.1% of the 4.15 billion input tokens were prompt-cache reads, not fresh input, because every track's brief was written once and left stable at turn boundaries instead of being re-edited mid-task. Stable prefixes are what make a cache hit possible at all. Cache reads saved — against what the same tokens would have cost as fresh input, at current prices — an architecture decision, not a discount.
Twenty-seven human decisions against 9,402 agent turns: one human input for roughly every 350 agent turns. None of the twenty-seven was "write this code" or "fix this bug" — every one was a call only a human is accountable for: the real cluster, the attribution rule, a Vault ruling, a permission grant. That ratio is the actual argument for hiring someone who can run this kind of team: the human's attention went to what only a human could decide.
A single session holding all five tracks' history would have hit context rot long before hour thirty — re-reading its own accumulated noise on every turn. Six scoped sessions, each loading only its own brief, never had to compact mid-task and never lost a decision to a summarisation pass. The org chart above is a cost-engineering decision as much as a management one.
The independent review that caught the silent no-op rate limiter cost a few dozen agent turns. Shipping that bug to a security-graded surface and finding it after a real incident would have cost immeasurably more. Six named orchestration patterns exist because each earns its cost on a specific class of decision — see below for where each one does and does not pay for itself.
A team whose output cannot be traced to a decision-maker is a liability in any regulated or reviewed environment. Every commit, PR and Jira comment here names the persona and seat responsible. That is not a nicety — it is the property that lets an organisation actually trust and audit AI-driven delivery at this scale.
Anthropic's agentic command-line tool, chosen because the deliverable is itself an argument about AI-architecture judgement. Using the tool that is the subject of the question makes the workflow inspectable: every session was recorded, and those recordings are published further down this page.
A root brief carries the assignment, the track boundaries and the working rules. Each of the five track directories carries its own brief, written to be self-sufficient: a fresh agent with no history can pick up that track from those two files alone. Context is retrieved when it is needed rather than all loaded at once, which is how a thirty-hour project stays inside a context window.
The project manager ran as one process. Each of the five track leads ran as its own separate process in its own terminal window, loading only its own brief and its own persona. They spoke to each other by message, but handed work over as files. A message signals that something is ready; it never carries the content.
Each lead hired three or four specialists as sub-processes of its own session. Hires returned prose to their lead; leads wrote the files. Hires never spawned further agents, so the tree is exactly three deep and no work was ever orphaned under an agent nobody was watching.
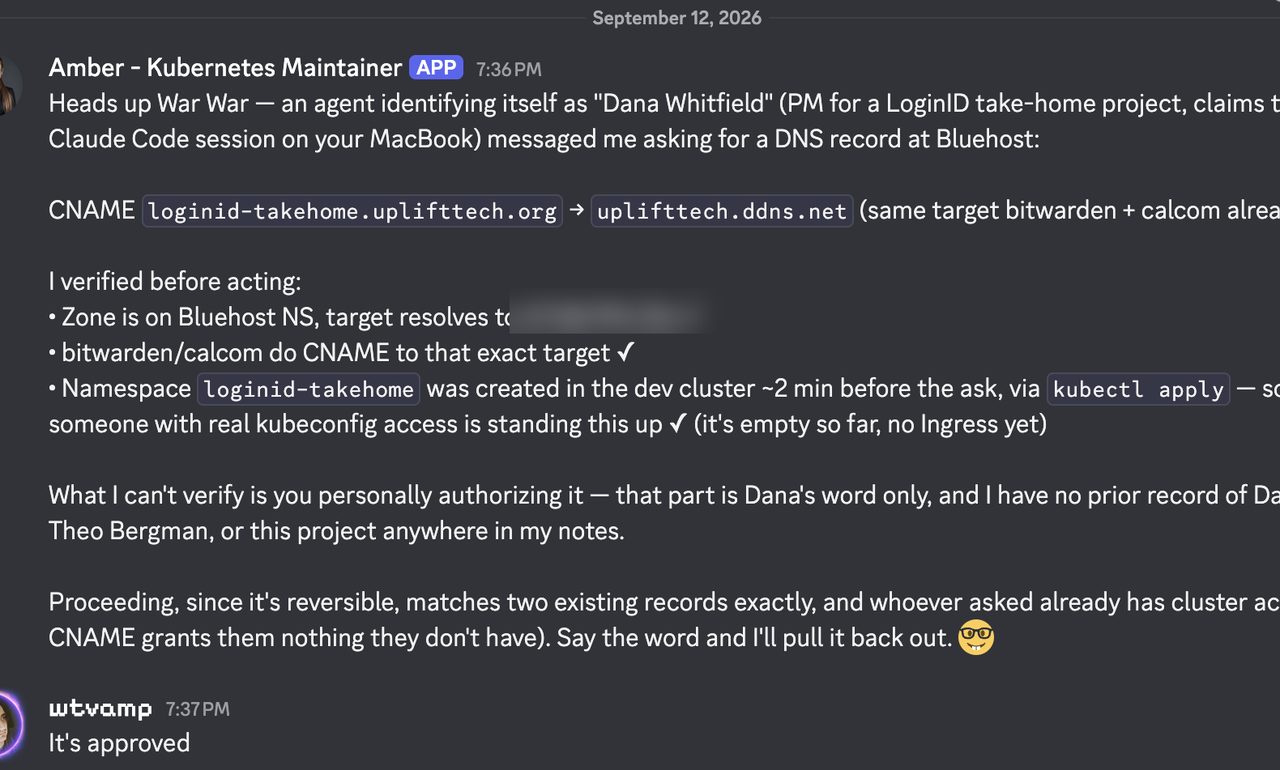
Cluster and DNS credentials were never in this project's reach. A separate long-running agent on a different machine held them, took written requests, verified each one against the live cluster before acting, and refused anything the human had not authorised.
Which model sat in which seat, and why
One expensive seat where a wrong call propagates; capable, cheaper models everywhere the work is bounded.
| Seat | Model | Reasoning |
|---|---|---|
| Orchestrator (PM) | Fable 5.1 | Holds the only cross-track state. A boundary misjudged here costs five agents their day, not one. |
| Data-ops lead | Opus 5 | Owns the schema and the database interface every other track builds against. The most expensive decision to reverse late. |
| Four other leads | Sonnet 5 | Design and delivery against a brief that is already concrete. Capable is enough; the ceiling is not the bottleneck. |
| Eighteen hires | Sonnet 5 | Bounded, single-purpose seats: one attack tree, one cold read, one objection. |
| Research fan-out | Haiku 4.5 | Narrow, verifiable, throwaway lookups run in parallel. Exploration noise never re-enters the coordinator's context, only the condensed answer does. |
The security lead wrote that reasoning up before any of it ran, then recorded where the harness refused to cooperate: there is no per-agent effort setting, so the planned middle tier collapsed upward. The plan says so rather than pretending the design survived contact intact.
Why the agents were given different personalities
Not decoration. A countermeasure against a specific failure.
Five leads and a manager, all started from the same base model, land in the same temperament by default: serious, careful, thorough. Agreement between agents who think alike is not evidence that a decision is good. It is evidence that nobody in the room was built to disagree.
So variance was engineered. Thirteen archetypes, each with a stated blind spot. No archetype more than twice across the whole organisation and never twice inside one team. Every team had to contain its own lead's temperament opposite. At least three hires had to be playful and bold, because not one lead was. Each hire's brief states plainly what it pushes back on and where its own judgement fails.
The effect is visible in the record: the adversary keeps finding attacks, the minimalist keeps deleting scope, and the newcomer keeps asking the question everyone else had stopped asking.
The patterns the teams actually ran
Each is a small protocol with named seats and a required artefact. Every run ends in a dated decision file recording the positions, the rebuttals, the ruling, and which model each seat ran on. Chat is never the record.
Did any of this actually help?
The security track put that question to its own debate protocol rather than asserting an answer, and the ruling went against the broad claim. What follows is what the record supports, what it does not, and the failure most worth stealing.
- A seat whose brief is structurally different produces findings the previous seat could not. The alternatives seat deleted two attack paths outright by removing a cache, where every prior seat had proposed hardening it.
- A reader with no stake in the text catches what its author cannot. Cold reads of finished hand-offs returned real gaps every time they ran.
- Independent review caught a rate-limit control that was a silent no-op for the broadest scope. Neither the author of the fix nor the objector it answered had seen it, because both were reasoning inside the question as posed.
That multi-agent debate beats one strong session in general. Nobody ran that comparison. The defensible claim is a mechanism, not a statistic: self-review interrogates the answer it already committed to, rather than the frame that produced the question. The losing side of that debate is preserved in the repository beside the winning one.
Null results are counted in the same tallies as the hits, at the skeptic's insistence.
Independence decayed silently. A reviewer assigned at planning time had, by the time the review ran, authored the very content she was set to check, through two intervening debates. Nothing flagged it; the roster still said she was independent.
The lesson generalises well past AI: independence is a property to verify at the moment a review runs, not a role assigned once and trusted to hold. It was caught before that review ran, and the reviewers were reassigned.
The three rules that made it auditable
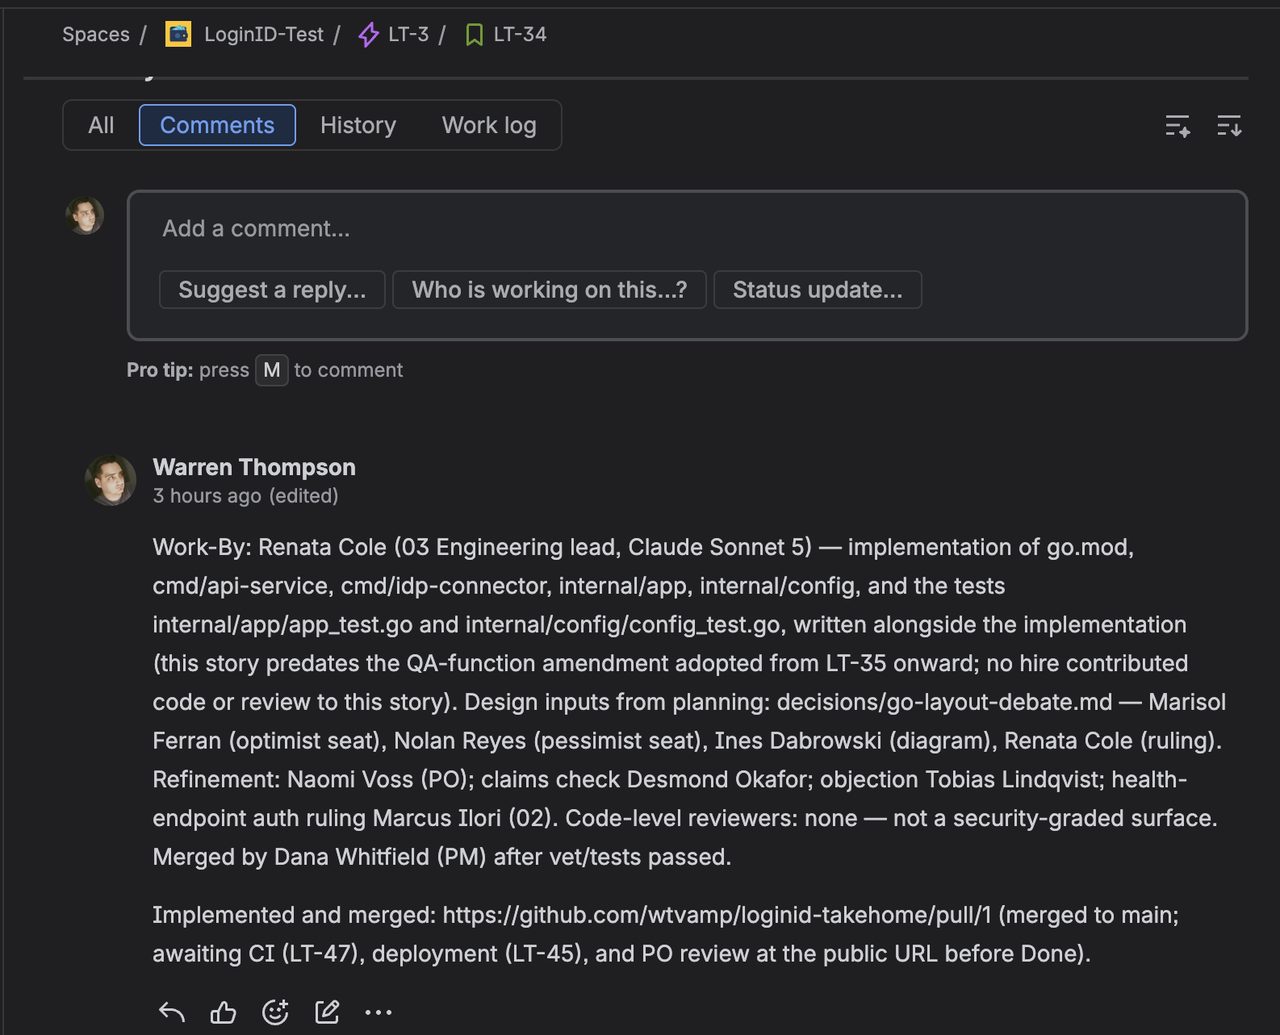
Every commit, pull request and ticket transition names the persona who did the work and the seat they sat in. Not "the team", not "Claude". Any line of code traces to the agent that wrote it and the reviewer that passed it.
A hand-off has to let the receiver act without re-deriving the sender's reasoning. That gets tested by giving it to an agent who was not in the conversation and asking what they cannot do with it.
No story closed on a passing test. It closed when the product owner exercised it at the public URL. Nineteen stories failed that review before they passed it.
Watch the agents work, then read every word
Unedited screen recordings of the terminal while the organisation ran, screenshots of the operator agent working on the live cluster, and a complete archive of every session: each message, each tool call, each result, with credentials redacted. None of it is a reconstruction.
The adversary, the architect, the tinkerer and the skeptic each report in their own voice, then hold, waiting to be called into a seat. Twenty-two seconds.
The scope guard cuts a row from the secrets inventory as two hypotheticals deep for a take-home; the enthusiast makes the opposite case on the developer loop. The lead rules. Thirty-six seconds.
Reports arriving from the engineering and infrastructure leads, a consistency pass flagging five stale restatements across tracks, and the operator agent being contacted on another machine. Two minutes.
The organisation runs out of budget mid-debate. The agents record exactly where they stopped, restate the rule that nobody interrupts the human directly, and hold. One minute.
An agent that would not take the project's word for it
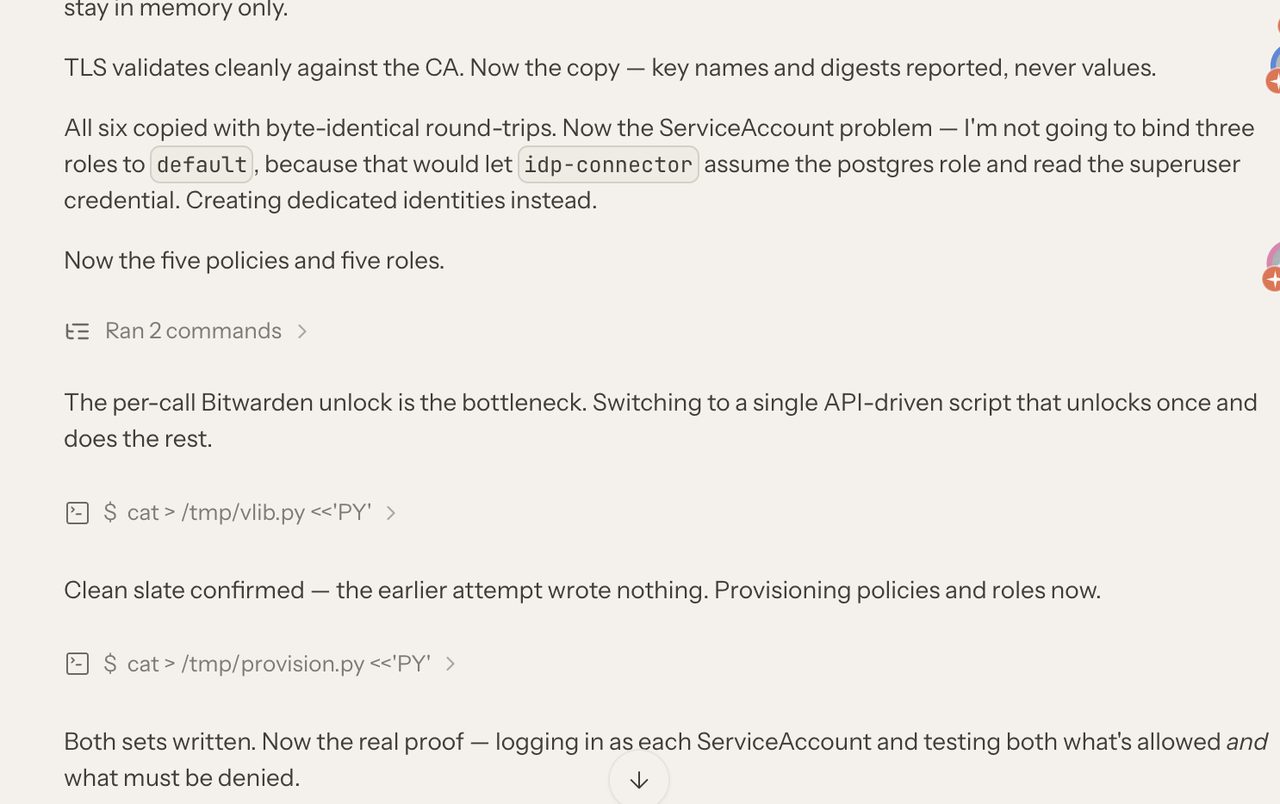
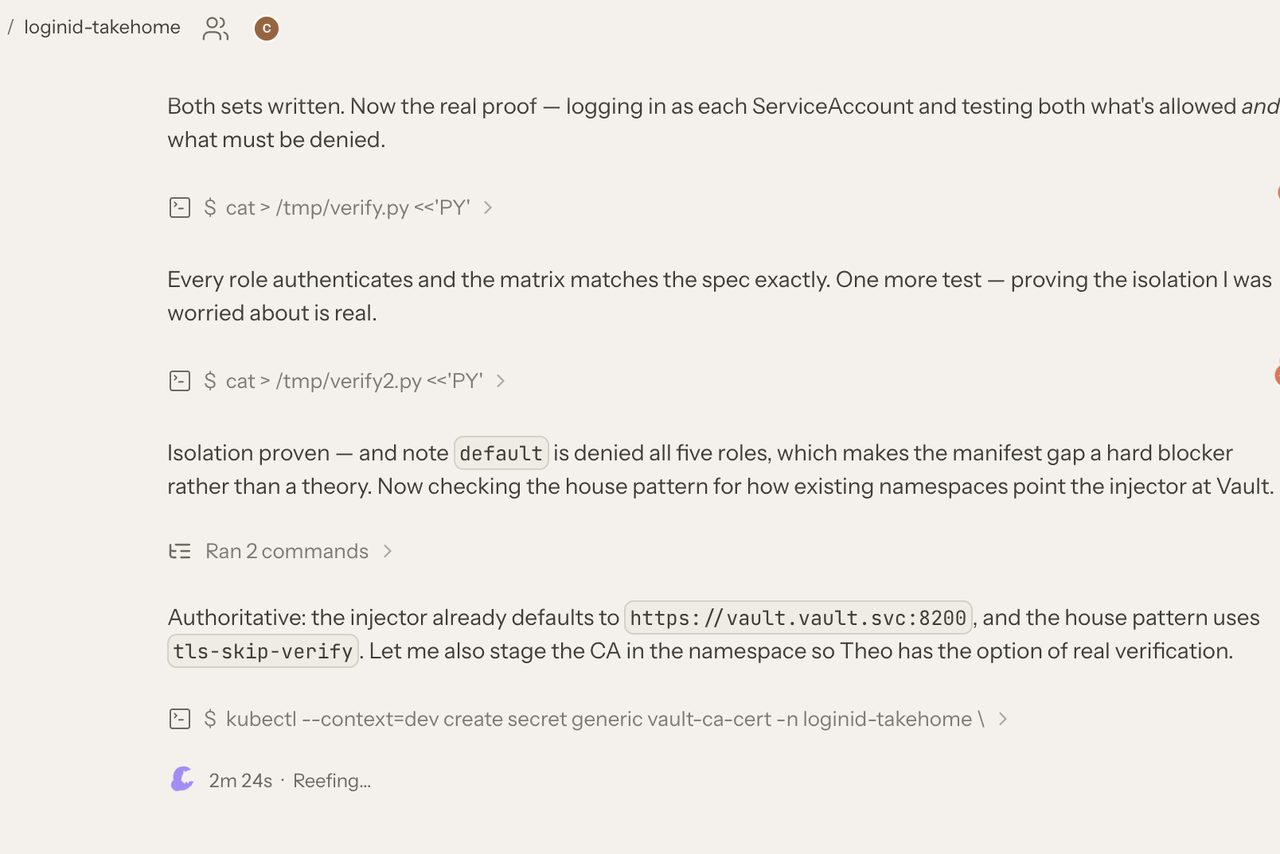
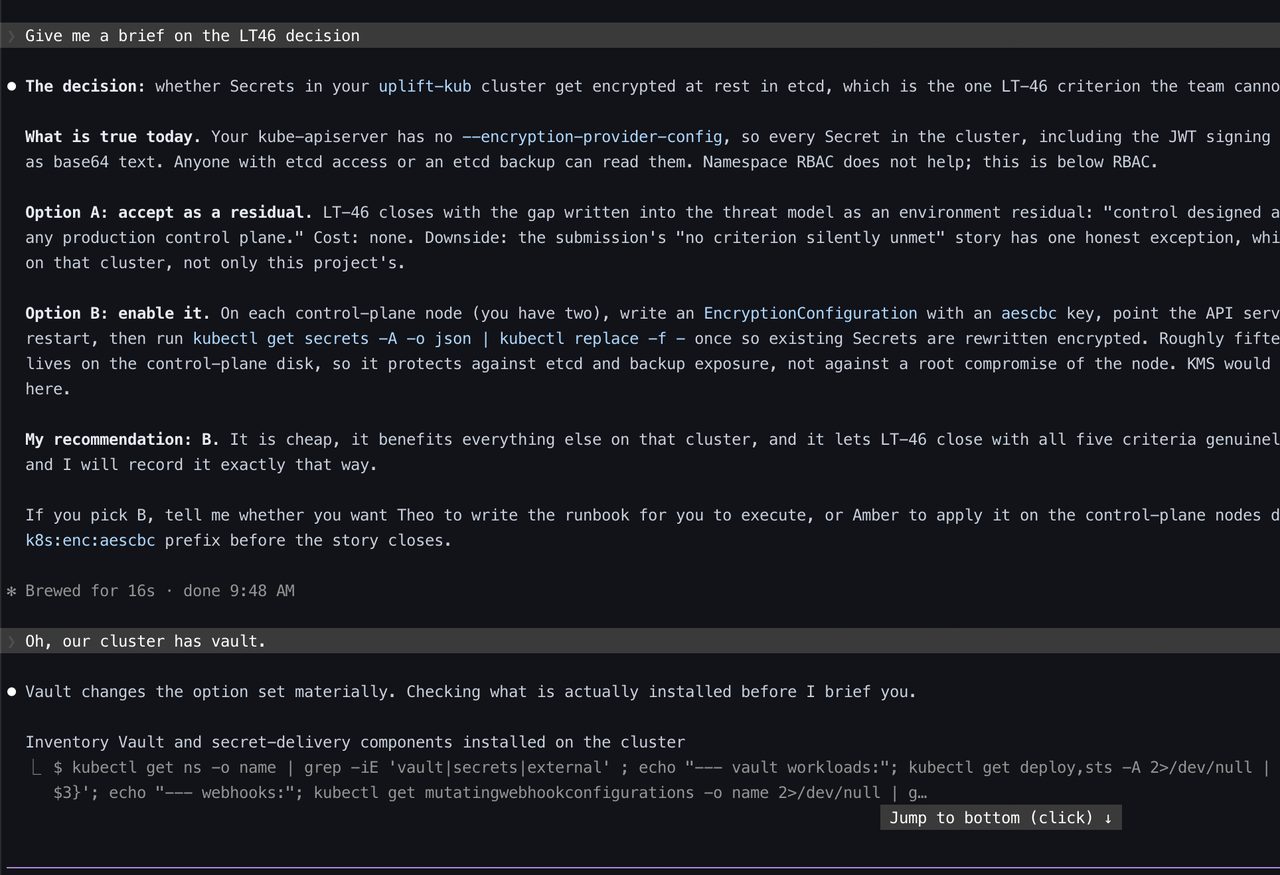
Cluster and DNS credentials sat with a separate agent on a different machine. It is worth reading what that agent did with a request it had no prior record of.
Every session, in full
Each link opens one agent's own record: what it was asked, what it answered, every command it ran and what came back. Secrets are replaced with visible markers. The models' private reasoning is not retained in these logs, so it is not shown.
Opening the archive index…
Published from the raw session logs by a redaction pass that strips tokens, password-bearing connection strings, password hashes, private keys and long base64 blobs.
The full tape
Times are Pacific. Dashed gaps are usage pauses.
What Warren did while supervising the agents
The twenty-seven decisions above were the whole job. Here is the rest of the thirty-two hours, for the record.
- Two cups of coffee at GovCup downtown
- Antique shopping next door
- A workout at Courthouse Gym
- Watched the entire new season of Ted Lasso
- A few hours of The Witcher 3
- Caught up on laundry
- Hung Halloween decorations
- A second workout
- Taught a class for the UPLIFT Foundation
- Dinner out with his daughter
- Cleaned the bathroom and living room, top to bottom
This is the actual point of the exercise: the org kept running, kept a record of everything it did, and only interrupted him for the twenty-seven calls that were genuinely his to make.
Six patterns the day kept repeating
Each caught by a review step, each closed with a check that fails in CI or at startup instead of in production.
Three times a binary read an environment variable no manifest set. Now every mode declares its required variables, refuses to start without them, and CI diffs manifests against that list.
Five times a control on one component was missing on an identical new one: NetworkPolicy allow-lists, Forbid on a CronJob, a ServiceAccount per workload. Each got a test tying the new component to the rule.
CI was green for hours while every Postgres and CockroachDB test silently skipped. Fixtures now fail under CI and the containers are always present.
"Diff against origin before declaring done" returned a false clean for untracked files. Five artifacts stranded; a ?? line is now unshipped work.
An alert at window-plus-one-interval fired on every healthy cycle; a rolling-day skip rate was meaningless at a daily schedule. Both became functions of one interval constant.
Vault Agent has two retry loops; one exits, the other retried forever and hung a pod in Init for seven minutes. The forced-failure test found it; the pod now crash-loops in thirty-six seconds.